Teach it where to look
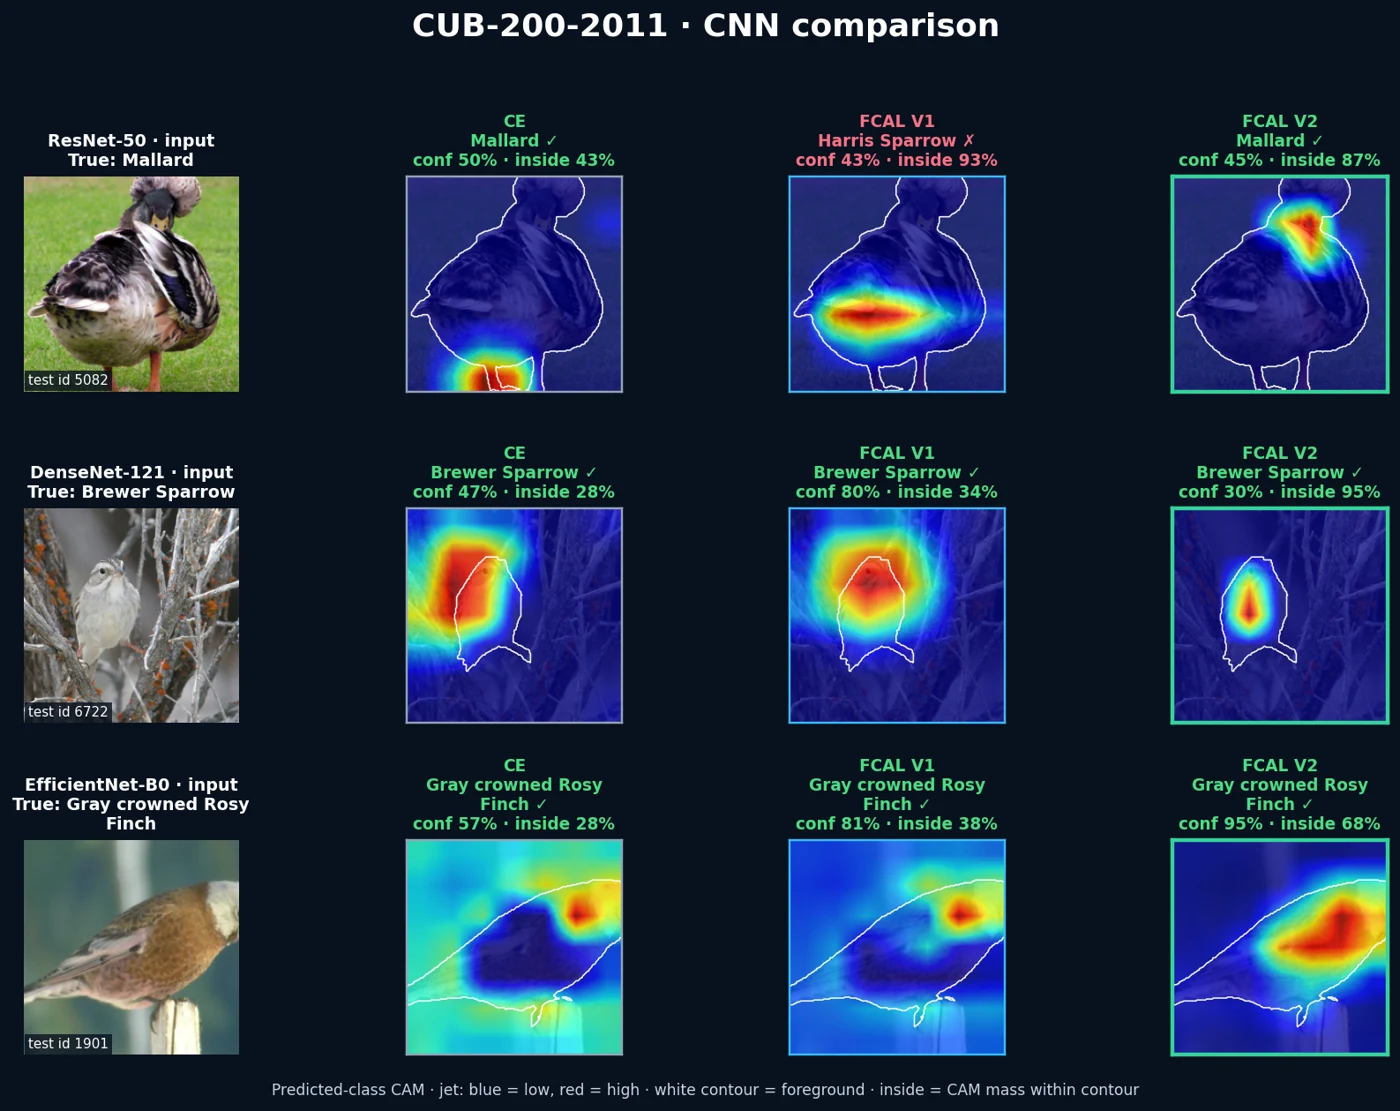
V2 combines a penalty for evidence outside the object with support for evidence inside it. CNNs and Vision Transformers use their own class-evidence adapters.
01 / Attention learning
Right answer. Wrong reason. Look at the bird.
A bird classifier can get the label right by looking at the scenery. FCAL asks a more interesting question: can we teach it to put its evidence on the bird itself?
Foreground-Constrained Attention Learning adds foreground supervision during training. The masks disappear at inference, leaving the same prediction interface and model size.
Research project / FCAL V2
V2 combines a penalty for evidence outside the object with support for evidence inside it. CNNs and Vision Transformers use their own class-evidence adapters.
The experiments compare clean predictions, class activation maps, and changed backgrounds. The bird benchmark includes three paired ResNet-50 training seeds.
Sharper localization does not guarantee higher accuracy. Results vary across datasets; the repository includes the ablations, baselines, and reproduction protocol.
Straight from the project.
Have something in mind?